
A skills gap analysis has worked if something changes at the end of it. Work gets reassigned. Somebody is handed a project they are not quite ready for. A hire gets approved, or a commitment gets dropped because you established that nobody can deliver it. If none of that happens, you ran a survey.
The standard output makes that unlikely. A grid of names against thirty or forty competencies, colour coded, technically complete, and impossible to act on, because it reports on everything at once and therefore on nothing in particular. Everyone agrees it was a useful exercise. Nobody opens it again.
The fix is not a better template. It is measuring a different distance.
Measure against the work, not against a framework
Almost every analysis starts from a list of skills that arrived from somewhere else: a competency library, a vendor, a job architecture project, a similar company's published model. The team gets rated against it and the gaps fall out.
The trouble is what those gaps mean. A framework describes an idealised version of the roles you happen to have, so measuring against it produces findings that are true in the abstract and irrelevant this quarter. You will discover that only two people are strong at advanced statistical modelling, and you will do nothing about it, correctly, because nothing you have committed to requires it.
Start at the other end. Write down what this team has actually promised to deliver in the next two quarters. Not the mission, not the strategy deck: the specific things that are on a roadmap or in somebody's plan, that a person outside the team is expecting. Then take each one and ask what has to be true about this team for it to happen, and which of those things is not currently true.
The list that comes out is short. That is the point, not a sign you did it badly. Five real gaps that block committed work can be decided on in an afternoon. Forty scored competencies cannot be decided on at all, which is why they get filed.
How to run it in about a week
Six steps, and the order matters more than the tooling. A shared document is enough for a team of ten.
- Name the work. Five to eight things the team must be able to do in the next two quarters, written as deliverables somebody is waiting for rather than as themes. If you cannot name five, that is a planning problem to fix before this one.
- Turn each into capabilities, at the level of somebody could do this without supervision. "Knows SQL" is not a capability. "Can take an ambiguous request from finance and come back with an answer they will act on" is, because you can tell whether it happened.
- Rate on evidence rather than opinion. Four levels are enough: has never done it, has done it with help, does it alone, can teach it. The rating is the output of a question about the past, not a number somebody picks.
- Find the single points of failure before you look at any average. A capability where exactly one person is above has done it with help is the most urgent thing on your list, and it is the finding an averaged chart hides best.
- Sort each gap into one of the three kinds below, because they need different answers, and decide per gap: build it, buy it, borrow it for now, or drop the commitment that needs it. Every gap gets one of those four, including the ones you choose to live with.
- Put a date on the re-check, tied to the next planning cycle rather than to the calendar. The analysis expires when the commitments change, which is the only thing that made it decidable in the first place.
Three kinds of gap, three different answers
They look the same on a chart and they are not the same problem.
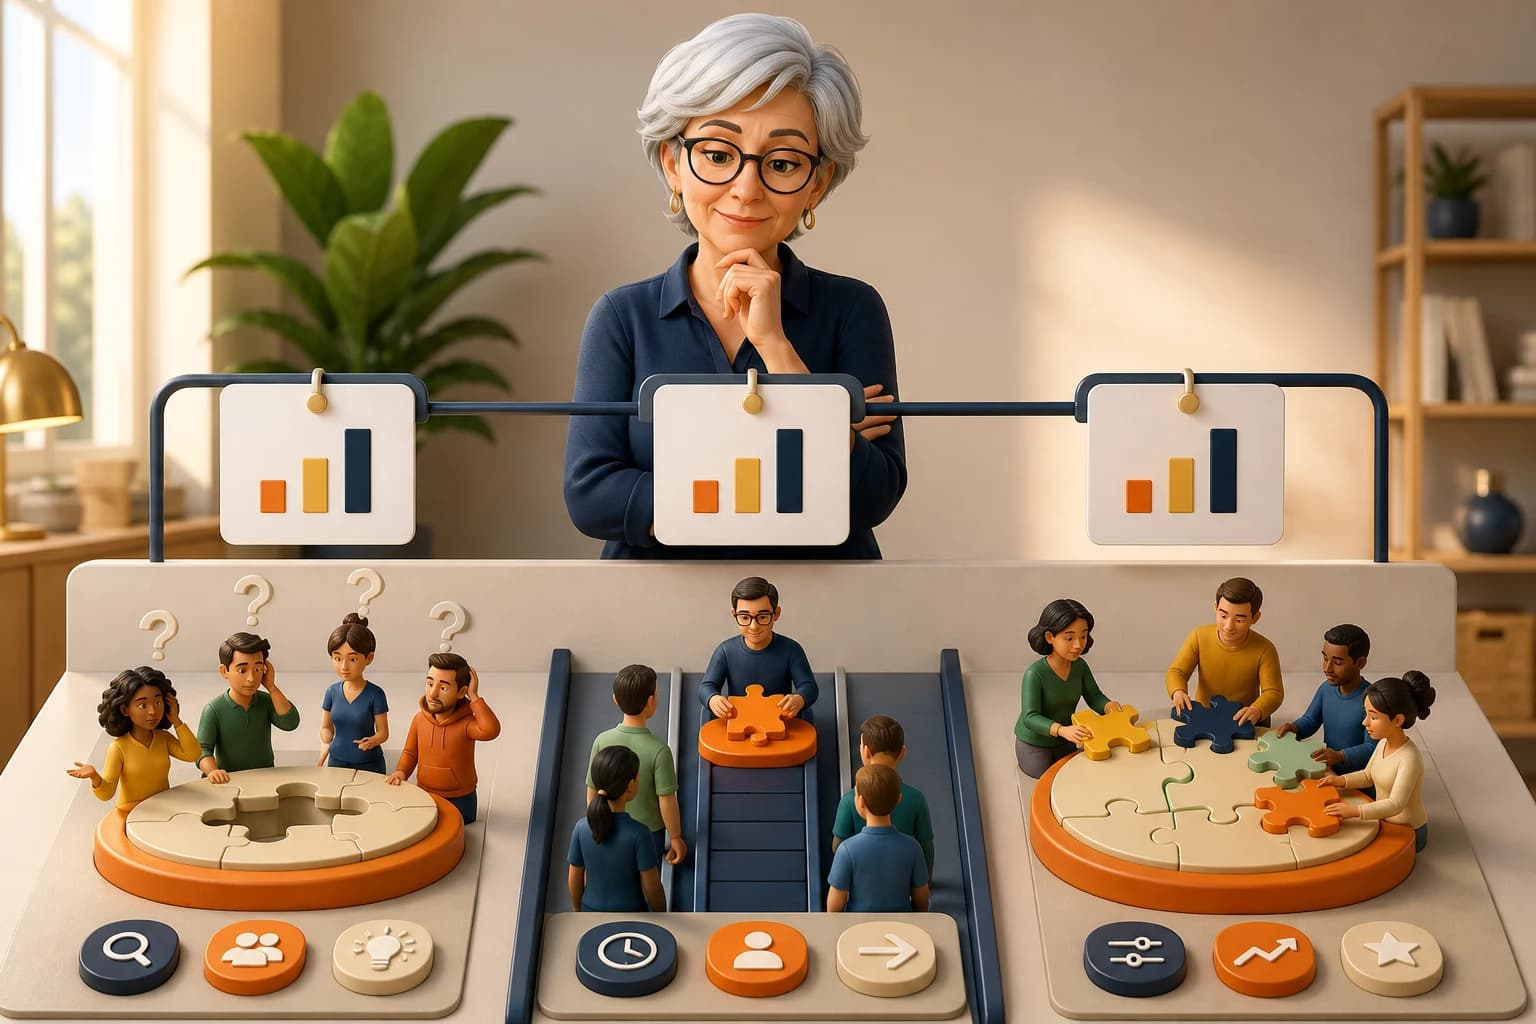
Nobody on the team can do it. This is the honest one, and the decision is a resourcing decision rather than a development one. Bring it in, or pick one person, fund a real attempt, and say out loud beforehand that the first attempt will be slower. What you cannot do is put it on a plan and hope.
Exactly one person can do it. This is the dangerous one, because on a competency chart it reads as coverage. In practice everything queues behind that person, they are interrupted constantly, and the risk arrives with a holiday or a resignation rather than gradually. The answer is a deliberate second person, and it costs the first person real time to teach, which has to be budgeted rather than assumed.
Everybody half does it. This is usually not a training problem. When results vary by whoever picked the work up, what is missing is an agreed definition of good, and a course will not supply one. A worked example that everybody has seen, plus one review step, fixes more of this than a term of learning content.
Where self-assessment goes wrong, and the question that fixes it
Ask people to rate themselves from one to five and you get numbers that cannot be compared, because everybody is comparing against a different reference. Some people rate against the best practitioner they have ever worked with. Others rate against the person sitting next to them. The same three means two different things on two rows of your spreadsheet, and comparison across people was the entire purpose.
Ask about events instead of levels. When did you last do this without help. What was the outcome. Who checked it, and what did they change. What went wrong the last time. Somebody who cannot name an occasion has answered the question without having to rate themselves, and somebody who names one gives you a fact you can weigh.
This also defuses the political problem, which is real and usually unspoken. In most organisations admitting a gap in a rating exercise feels like volunteering for a bad review. Admitting that you have not personally run one of these yet is a statement about your history rather than about your worth, and people will say it.
The same applies to how the result is used. If the analysis quietly becomes an input to performance ratings, you will get accurate answers exactly once.
What AI changes, and the part it flatters you on
Two things get genuinely cheaper. The first is assembling the evidence: pulling project history, review notes, who actually led what, and what somebody has been asked to do twice, into one picture per person, then clustering it into themes. That work is tedious rather than difficult, which is why it never gets done properly, and volume is what machines are for.
The second is writing the capability statements. Turning "be more commercial" into something observable is a language problem, and these models are good at it, particularly if you push back on the first answer whenever it is another adjective.
The part to be careful about is that a model will cheerfully hand you the forty-competency framework. It has seen a great many of them, it can produce a complete and plausible one for your industry in seconds, and a complete-looking framework is precisely the failure this exercise exists to avoid. It does not know what your team has committed to unless you tell it, and the commitments are the only thing that makes the list short enough to act on.
So give it the work first, ask what capabilities that work implies, and then ask it to argue against its own list: which of these would a sceptical person say we already have, and which are we calling a skills gap to avoid calling it a priorities problem. It is a better critic than author here.
The test of whether it worked
A month later, three questions. Did any commitment get renegotiated because you established that nobody could deliver it. Did anybody get handed work they were not quite ready for, with the slower first attempt agreed in advance. Did a second person start learning the thing that only one person can currently do.
If all three answers are no, the analysis may have been perfectly accurate and it was still useless. That is the normal outcome, and it is not caused by bad analysis. It is caused by an exercise that produced a description when it needed to produce decisions.
The deliverable is not the chart. It is a small number of decisions somebody can be held to, and the chart is the thing you throw away once they are made.